arXiv preprint 2607.22034, 24 July 2026
Small Vision-Language Models Know When They Are Wrong But Cannot Say So: A Two-Model Study of Stated versus Internal Confidence Under Realistic Image Degradation
M M Asif Ferdous
Small vision-language models carry useful knowledge of their own mistakes in their token probabilities, even when the confidence they state in words is almost useless.
I tested two small open-weight models, Qwen2-VL-2B-Instruct and SmolVLM-Instruct, on images degraded by compression, camera shake and poor lighting, across 3,800 predictions.
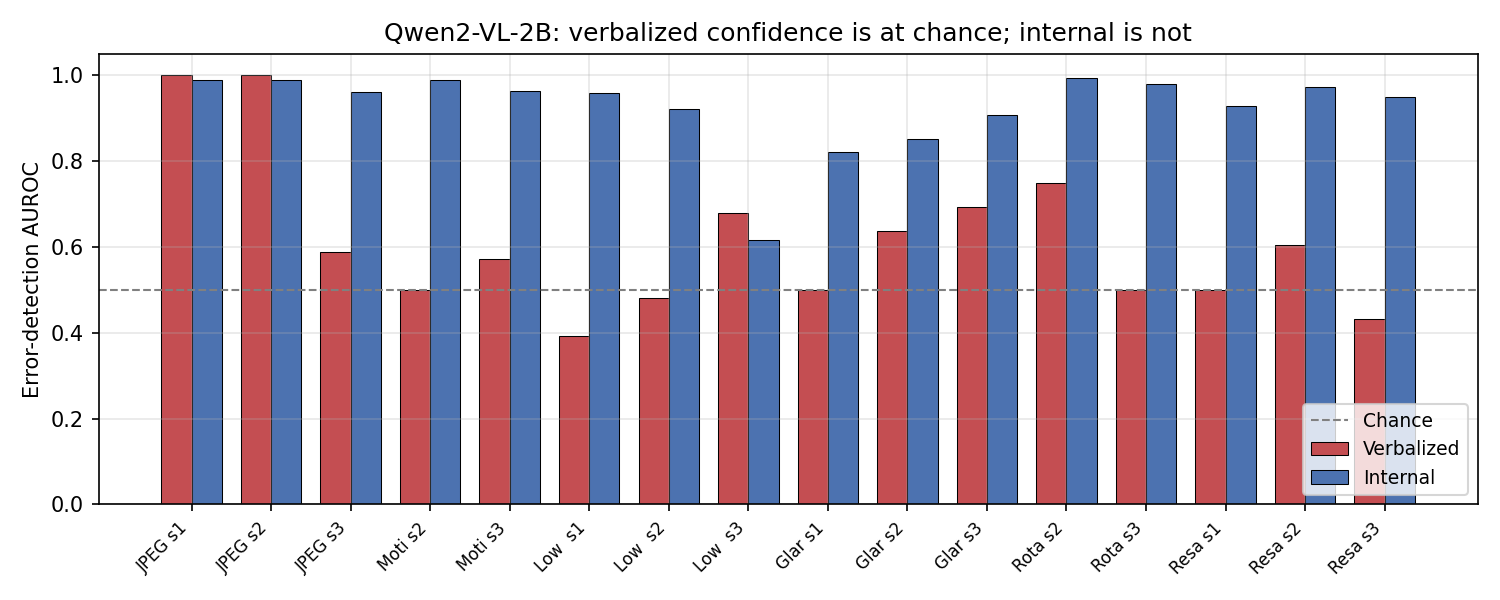
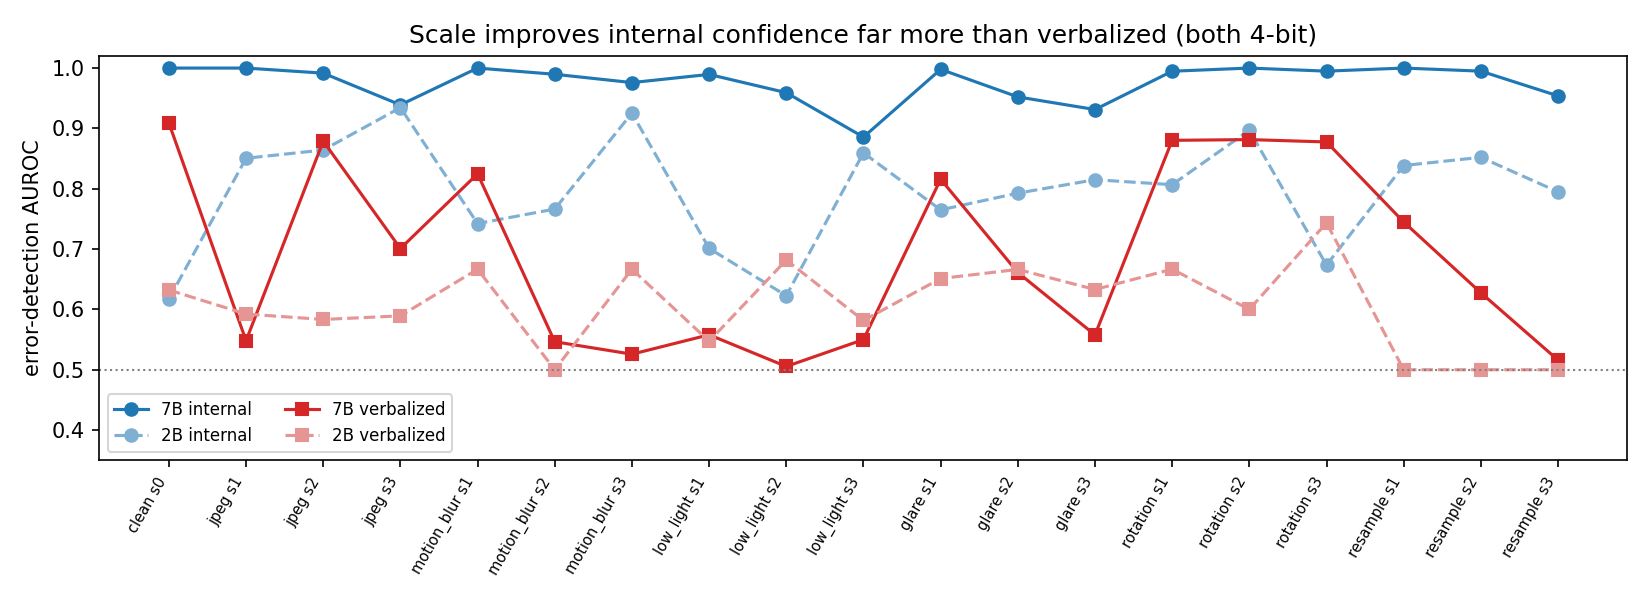
The confidence the models state in words barely tracks whether they are right. Their internal token probability detects errors well, which makes it the better signal for deciding when a model should hand over to a person. Under severe low light, neither signal can be trusted.